

Stop Retyping Documents Into Your Systems by Hand
Every invoice, form, contract and application that arrives as a PDF or a scan usually ends up retyped into an ERP field by field. Document AI reads the document, pulls out exactly the fields you need, shows the source next to each value so a person can confirm it in seconds, and posts the confirmed data directly into your system.
50+ ERP and software projects. Zero failed projects since 2021.
The document was already digital, the retyping wasn't
A PDF invoice already contains every field your ERP needs. Someone still opens it and types the numbers in twice.
Handles the messy formats that actually show up
Real documents are not clean templates. A scanned invoice from one supplier and a native PDF from another look nothing alike, yet both need the same fields pulled out. The extraction is built and tested on your own real document mix, not a tidy sample.
- Scanned images, photos and native PDFs all handled.
- Tested against your own real document variety.
- Layout differences between senders handled directly.
Confirm in seconds, not re-read from scratch
Every extracted field is shown against the exact spot in the source document, so confirming it is a glance, not a re-read. Low-confidence fields are flagged clearly, so a person's attention goes to the handful of values that actually need checking.
- Extracted value linked to its exact source location.
- Low-confidence fields flagged for a closer look.
- High-confidence fields ready to post without delay.
What a processed document looks like
The document, the fields pulled from it, and the confidence flag before anything is posted.
From a document arriving to data posted in your system
The documents most companies process by hand
We start with your highest-volume document type, then extend to the rest.
Invoices and bills
Vendor invoices in any layout, with line items, taxes and totals extracted for posting.
Purchase and sales orders
Order documents from customers or suppliers, extracted directly into your order system.
Contracts and agreements
Key dates, values and clauses pulled from contracts for tracking and compliance.
Applications and forms
Job applications, credit applications or onboarding forms extracted into your workflow.
Shipping and customs documents
Bills of lading, packing lists and customs paperwork read for the fields logistics needs.
Compliance certificates
Certifications and licenses checked for validity dates and required details.
What document AI changes
Why teams choose TCB Infotech for document AI
Document AI questions
What is document AI?
What document formats can it handle?
How accurate is the extraction?
Does it post directly into our ERP?
Can we see what was extracted from where?
How long does a first extraction workflow take to build?
The data was never missing, it was just locked in a PDF
Every document your business processes already contains the fields your systems need. The only step that was ever missing was a reliable way to pull them out without a person retyping every one.
Document AI fills exactly that gap: it reads the document, extracts the fields, shows its confidence, and leaves the final check to a person on anything uncertain. The document does the same job it always did, just without the retyping.
Stop Retyping Your Highest-Volume Document
Book a free consultation. Bring a sample of the document your team processes most, and we will show you what automated extraction would look like.
Book a Free Consultation →No commitment. A practical look at your document volume.
What Is Inside a Document AI Workflow
Extraction is only useful if it can be trusted at a glance. Here is how layouts are handled, how confidence is scored per field, and how a confirmed value reaches your ERP.
From a scanned document to a confirmed record
Built to handle documents that do not match each other
The same field, an invoice number or a delivery date, sits in a different place on every vendor's template. The extraction is trained to find the field by what it is, not by its fixed position, so it holds up across the layout variety your inbox actually receives.
- Fields located by meaning, not fixed position.
- Multiple vendor and format layouts handled together.
- New layouts added as they appear, without a rebuild.
Every field graded, not just extracted
Each extracted value carries a confidence score based on how clearly it was read from the source. High-confidence fields move straight to posting, while anything below the agreed threshold is set aside for a person, so review effort concentrates where it is actually needed.
- Per-field confidence, not one score for the document.
- Threshold for automatic posting agreed with your team.
- Review effort concentrated on the fields that need it.
The same rules your ERP already enforces
Extracted values are checked against your existing validation rules, such as a valid vendor code or a matching purchase order, before posting. A confirmed record enters your ERP exactly as if a person had typed it, following the same checks and approvals.
- Extracted data checked against your existing rules.
- Posting follows your normal approval workflow.
- No bypass of controls your ERP already applies.
Everything the document AI build includes
Source highlighting
Each extracted field shown against its exact location on the original document.
Review queue
Flagged fields gathered in one place for quick confirmation before posting.
Duplicate detection
Checking a new document against records already posted to catch duplicate submissions.
Three-way matching
Cross-checking an invoice against its purchase order and receipt before it is approved.
Processing analytics
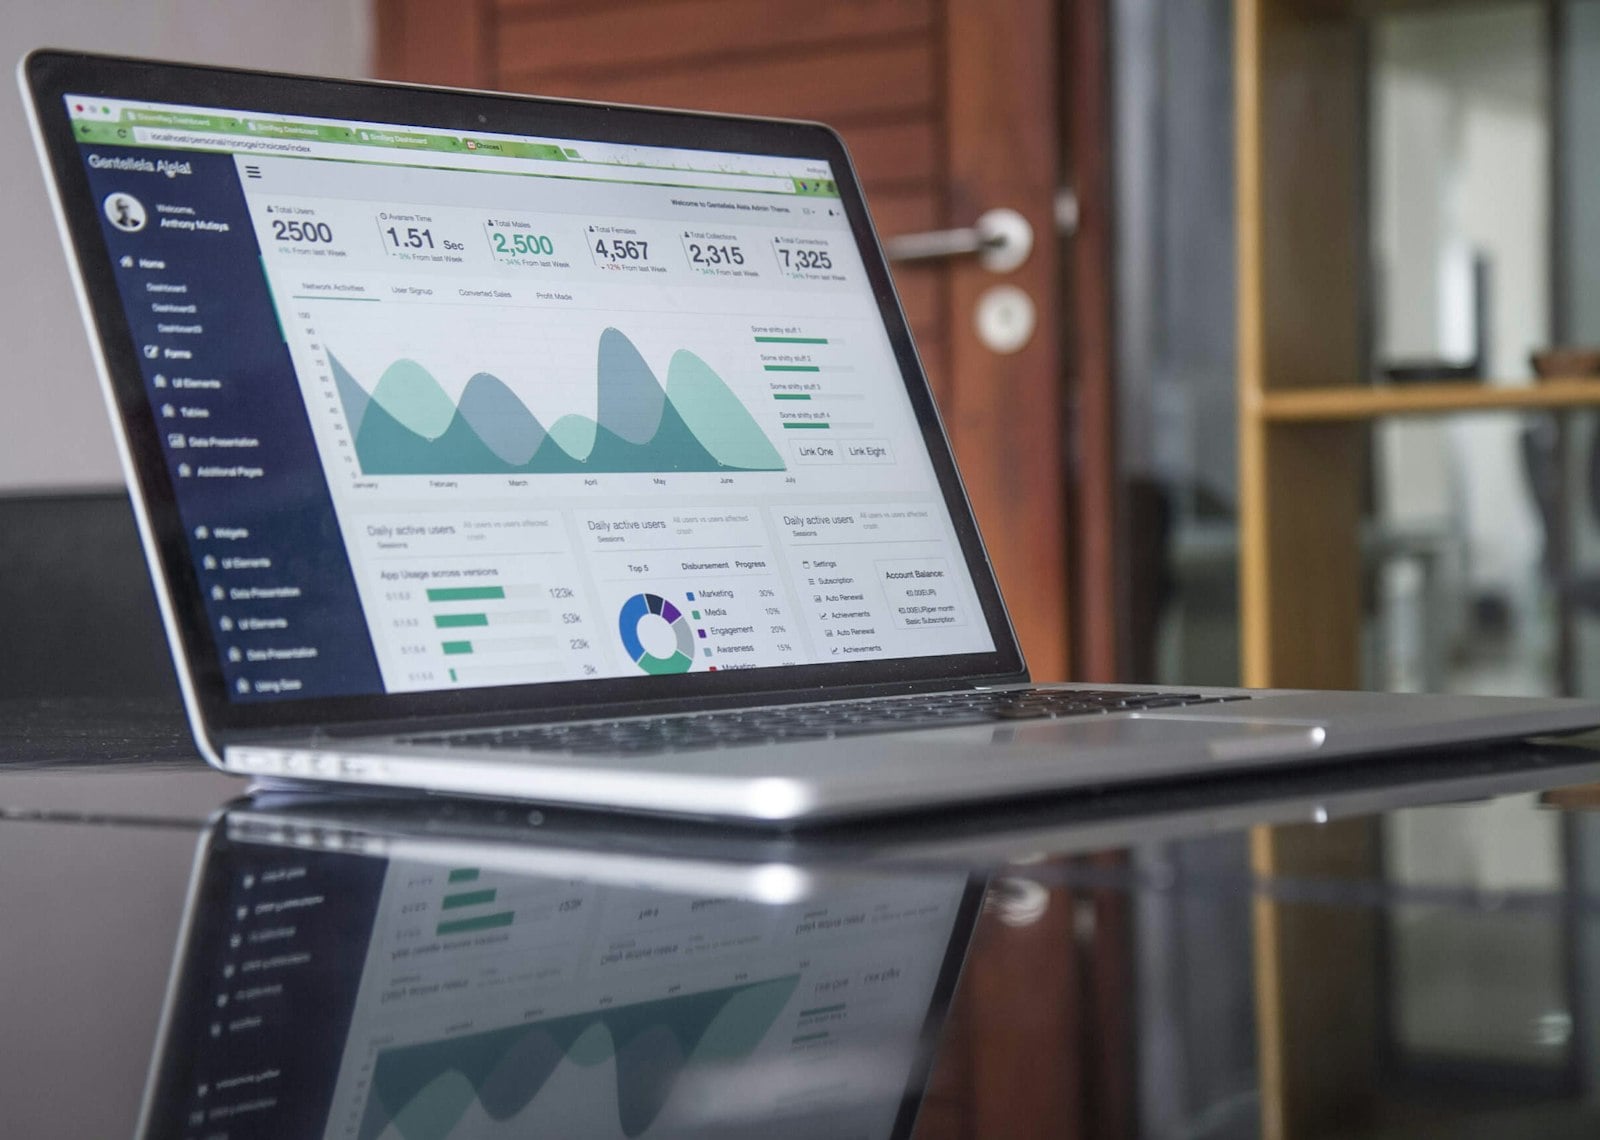
Volume, accuracy and turnaround tracked over time, by document type and source.
Model-agnostic build
Built so the underlying extraction approach can be upgraded without rebuilding the pipeline.